Goal Planner
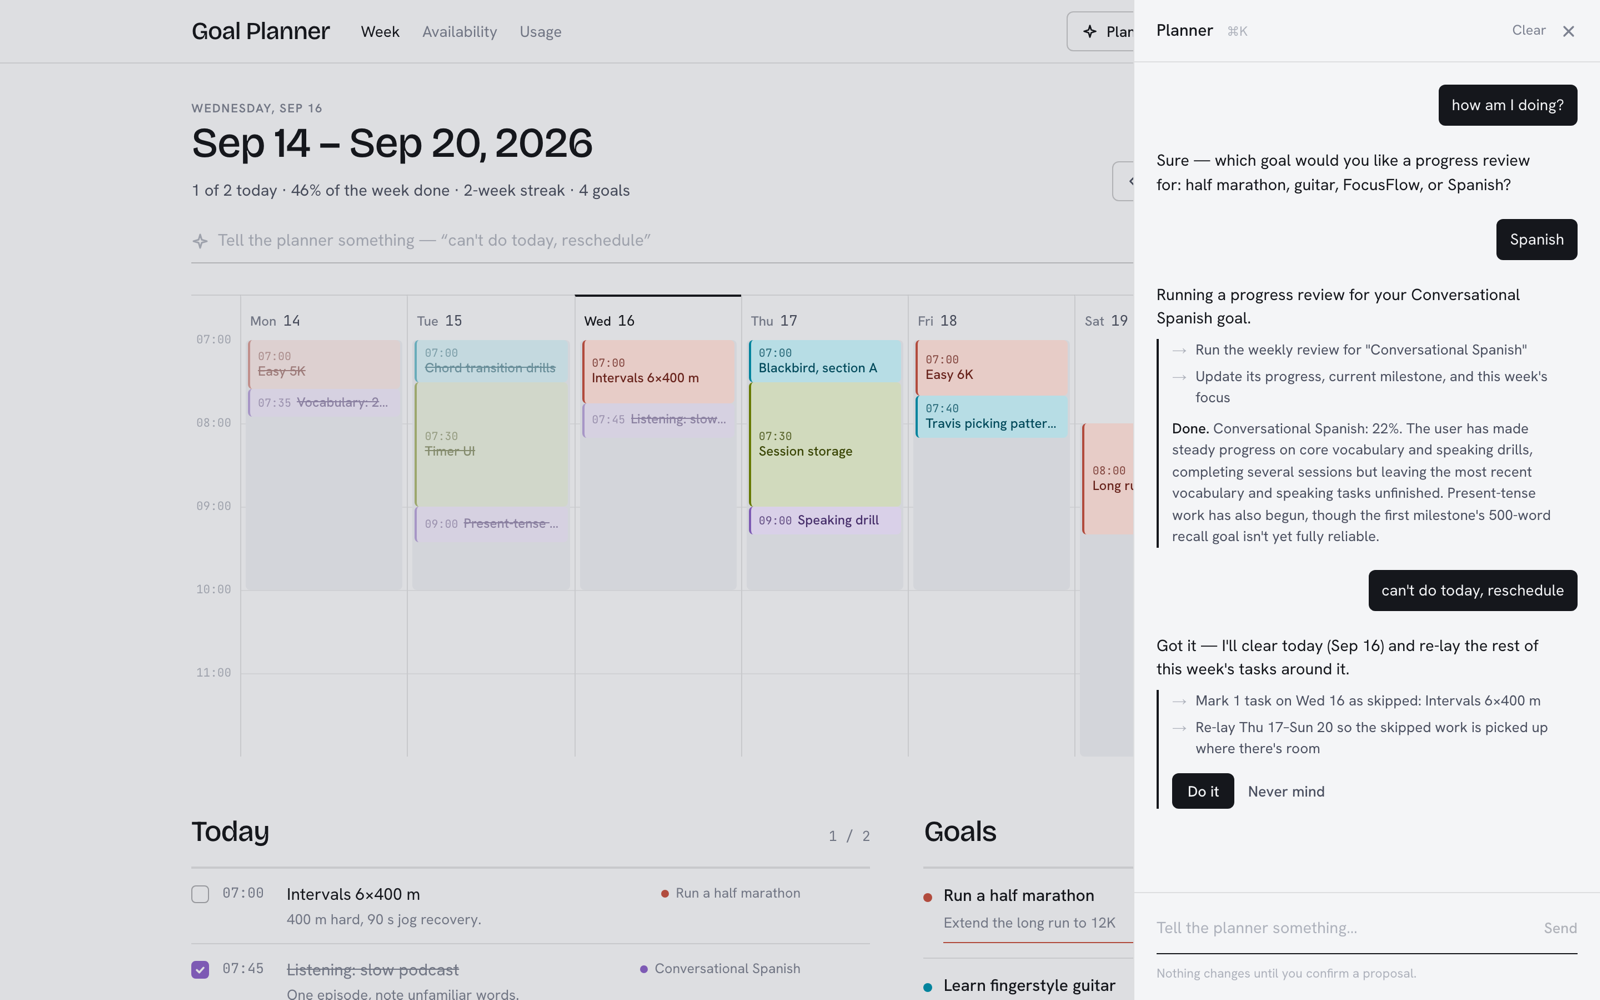
Type a goal in plain language and three Claude agents each do one job. The Architect builds a milestone roadmap. Progress reviews your week and adjusts where you are. The Scheduler places tasks into your available hours across every active goal. Structured outputs constrain every model call to a Zod schema, every agent has a deterministic fallback with typed failure reasons, and every plan is recorded as model- or fallback-generated, so the app keeps working when the model doesn't.
I built the measurement layer before anything else. Every call writes one row: model, source, reason, attempts, tokens in and out, latency, estimated cost. It's fire-and-forget and swallows its own errors, so it can never affect the call it describes. A usage page aggregates thirty days: cost per day, p50 and p95 per agent, fallback rate, and why calls fell back. Without that, a fallback and a real model response produce identical-looking rows and you're blind.
An eval harness runs 24 goals across 13 domains, plus two injection cases and one deliberately vague goal, through the real Architect: nine deterministic checks scored separately, then an Opus judge grading four properties on a written 1–5 rubric with the candidate delimited as untrusted and the judge told not to reward length. Result: Opus 5 scores 4.67 against Sonnet 5's 4.27, a paired difference of +0.39 ± 0.17 over 22 goals, at 2.6× the cost and 1.7× the latency. That's why the Architect runs on Opus and the cheaper agents on Sonnet. The caveat is stated in the doc: the judge is Opus.
The tooling found six bugs none of the tests could see. The schema said a milestone's week was when it was targeted, so the model read it as due and the app read it as start, and every model-generated roadmap failed ordering. "By end of year" produced 24-week plans against a 16-week deadline because the model has no clock. A replan that returned generic titles turned out to be a 39-second fallback with zero tokens: Opus 5 and Sonnet 5 think by default, thinking counts against max_tokens, and the SDK surfaces truncation as a parse error rather than a stop reason, so the retry never fired.
The routes are hardened the way a public model endpoint has to be. Every request body has a Zod schema with a maximum on every string that reaches a prompt, which is a cost ceiling as much as input validation. Model routes are rate-limited per user with atomic fixed windows in Postgres, and signup per IP. Everything the user wrote goes inside delimiters, closing-tag attempts are stripped, and every system prompt says to treat it as data; both eval injection cases are resisted by both models. 124 tests run in CI.
The repository is private while I'm still actively working on it. Happy to walk through it or share access — email me.